d-Matrix Adopts NVIDIA NVLink Fusion for Rack-Scale XPU Deployment
AI inference chipmaker d-Matrix will integrate its next-generation Raptor XPUs with NVIDIA's AI infrastructure platform using NVLink Fusion, aiming for accelerated, lower-risk, and scalable deployment of ultra-low-latency inference at rack-scale.
Intelligence analysis by Gemini 2.5 Flash
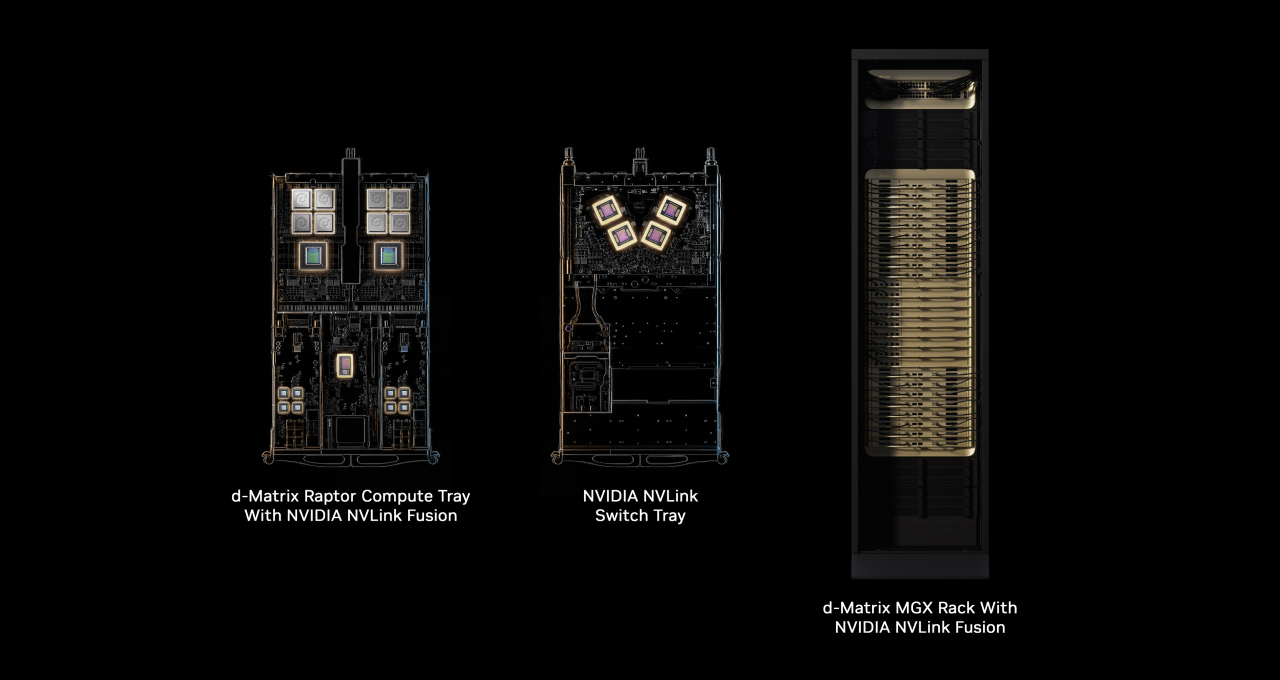
The article announces a strategic partnership where d-Matrix will leverage NVIDIA's NVLink Fusion technology and MGX rack architecture to deploy its custom Raptor XPUs. This collaboration allows d-Matrix to integrate its specialized inference processors into a proven, vertically integrated, yet horizontally open AI factory platform, streamlining the path from custom silicon to large-s…
Imagine building a super-fast brain for computers that helps them understand things really quickly, like recognizing pictures or understanding speech. Building just the brain chip is hard, but making sure it works with all the other computer parts in a huge factory is even harder. NVIDIA has a special "super highway" called NVLink Fusion that lets companies like d-Matrix plug their new brain chips right into NVIDIA's ready-made computer factories. This makes it much easier and faster for d-Matrix to get their super-fast brains working in big computer systems, so more people can use them for AI.
Analysis
NVLink Fusion
NVLink Fusion represents NVIDIA's strategic platform designed to seamlessly integrate third-party custom XPUs and CPUs with its established AI infrastructure, encompassing NVLink scale-up networking and the MGX rack architecture. This innovative approach directly addresses the formidable challenges faced by XPU manufacturers in deploying their specialized silicon at scale, effectively allowing them to bypass the intricate, time-consuming, and costly process of constructing rack-scale infrastructure from the ground up. By leveraging NVIDIA's globally deployed AI factory platform, partners like d-Matrix gain access to a proven, comprehensive ecosystem that spans critical components such as compute, networking, storage, security, power, cooling, and essential software.
The platform delivers substantial performance enhancements, notably achieving three times lower XPU-to-XPU latency compared to conventional off-the-shelf Ethernet solutions, alongside a remarkable ten times higher packet rate. Furthermore, it provides an impressive 3 TB/s per XPU of all-to-all bandwidth through its sixth-generation NVLink technology, ensuring the high-speed data transfer capabilities indispensable for demanding AI inference workloads. This integration capability is broadly compatible, supporting all major CPU architectures—including Arm, x86, and RISC-V—in conjunction with NVIDIA GPUs, thereby fostering a versatile and unified environment for AI factory operations.
d-Matrix
d-Matrix, a prominent AI inference chipmaker, stands as a key partner in the adoption of NVLink Fusion for its next-generation Raptor XPUs. Sid Sheth, cofounder and CEO of d-Matrix, emphasized the escalating demand for inference capabilities coupled with the inherent limitations of capital, time, and energy resources. He positioned NVLink Fusion and MGX as critical solutions to these industry-wide challenges, enabling d-Matrix to embed its specialized processors into a liquid-cooled architecture. This integration promises customers a significantly faster and lower-risk pathway for deploying and scaling ultra-low-latency inference capabilities.
Through standardization on NVIDIA's common rack architecture, d-Matrix ensures that its XPUs can operate harmoniously alongside existing NVIDIA GPU-based systems, such as the NVIDIA Vera Rubin NVL72, facilitating disaggregated inference. The company's integration strategy also includes plans for incorporating other NVIDIA components, including Vera CPUs, ConnectX-9 SuperNICs, BlueField-4 DPUs, and Spectrum-X Ethernet networking. This holistic integration provides d-Matrix with a robust and validated foundation for deploying specialized inference solutions within flexible, unified AI factories, thereby streamlining development complexities and accelerating its market entry.
AI Factories
NVIDIA's overarching vision for the "AI factory" is conceptualized as a full-stack platform engineered for complete fungibility, capable of executing every conceivable AI workload, model, and architectural design with optimal performance per watt and the lowest possible cost per token. This comprehensive platform integrates advanced components such as NVIDIA Vera Rubin NVL72, Groq 3 LPX, the Vera CPU rack, Vera BlueField-4 STX storage, and Spectrum-6 SPX Ethernet networking. NVLink Fusion plays a pivotal role in extending the inherent openness of this platform, granting customers the flexibility to precisely match the most appropriate compute resources to specific workloads within a unified AI factory framework.
The integration of third-party silicon, meticulously facilitated by NVLink Fusion, provides silicon innovators like d-Matrix with direct access to NVIDIA's extensive networking infrastructure, sophisticated systems, comprehensive software suite, and robust global supply chain. This strategic approach not only promises to enhance performance and significantly accelerate time to market for partners but also substantially mitigates the inherent risks associated with deploying semi-custom AI factories. The ability to standardize on a common rack architecture means that data centers can be constructed once to efficiently support a diverse array of processors—including GPUs, CPUs, and XPUs—eliminating the need for separate infrastructure designs for each processor type, ultimately leading to enhanced operational efficiency and scalability.
Key points
- d-Matrix is adopting NVIDIA NVLink Fusion for its Raptor XPUs.
- NVLink Fusion integrates third-party XPUs/CPUs with NVIDIA's AI infrastructure.
- It offers 3x lower latency and 10x higher packet rates than off-the-shelf Ethernet.
- The partnership aims to accelerate rack-scale deployment of ultra-low-latency inference.
- NVIDIA's MGX rack architecture and AI factory platform provide a proven foundation for integration.
This collaboration could significantly accelerate the deployment of specialized AI inference solutions by providing a standardized, high-performance, and lower-risk integration path for custom XPUs. It fosters a more open and diverse AI hardware ecosystem, potentially leading to greater innovation and efficiency in AI processing across various workloads.
While the article highlights benefits, relying heavily on a single vendor's infrastructure like NVIDIA's could create vendor lock-in for partners. Any future changes in NVIDIA's platform strategy or pricing could impact d-Matrix and other partners, potentially limiting their flexibility or increasing costs in the long run.